When we read text, we are essentially “taking in” information from a token stream, and information density
is uneven across that stream.
From the perspective of language, information content represents a word's surprisal, novelty, and
unexpectedness. Words that
are harder to predict from context typically carry more information. A simple example: "This morning I
opened the door and saw a 'UFO'." and "This morning I opened the door and saw a 'cat'." — clearly "UFO"
carries more information.
Important content must be hard to predict. The converse does not hold: what is hard to predict may still be
unimportant, as with random numbers—strictly speaking, Shannon information seems to represent the upper
bound on "importance."
Information-Theoretic Perspective
In this implementation, the information content of each token comes from how difficult it is for the LLM to
predict that token from left to right.
From an information-theoretic perspective, this can be expressed as the conditional information of a token
given the model and the preceding context:
Information of tokeni in a text=−log2P(tokeni| model, token0, …, tokeni−1)
The core assumption behind Info Highlight is that the magnitude of this conditional information is related
to human subjective perception—novelty, surprise, and potential importance:
Word importance in text≤conditional information of the token in the context
How Info Highlight works
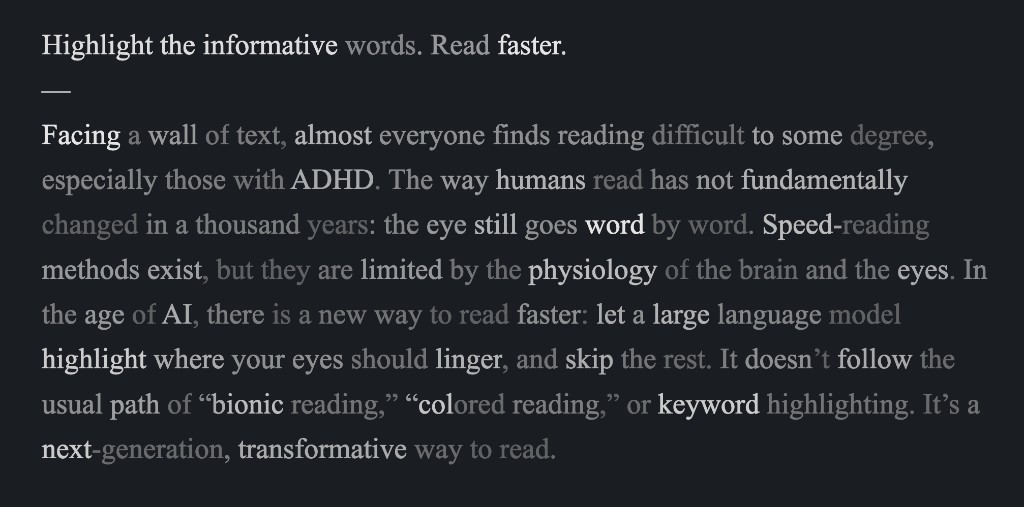
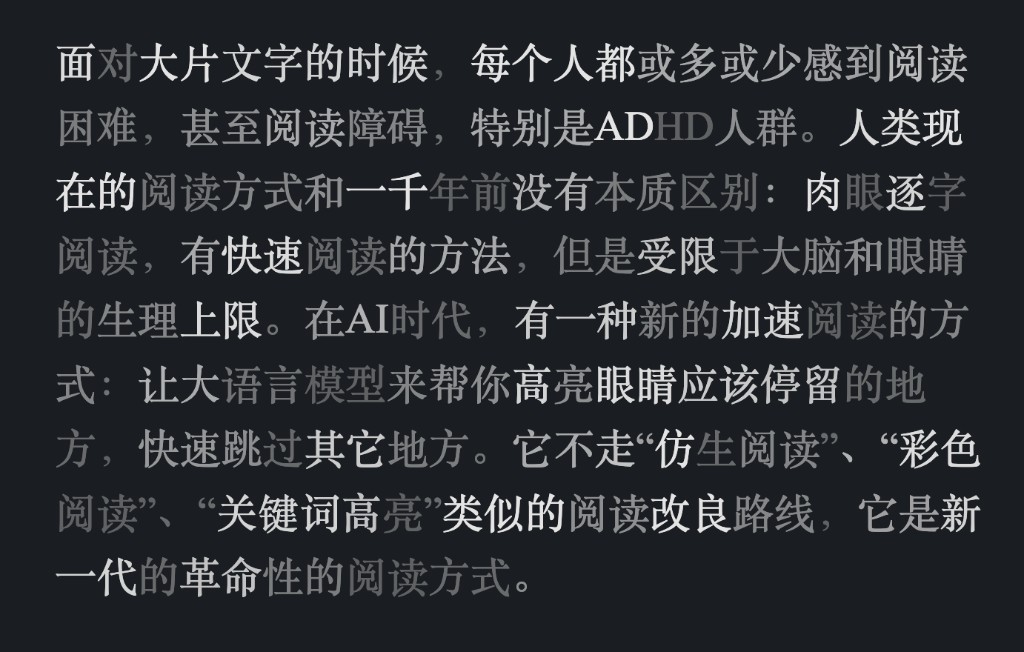
The Info Highlight extension uses a large language model to compute the surprisal of each word, and draws it
on web pages as an information-density heatmap. The lightness or depth of each word's color shows how much
information it carries.
The harder a word is to predict from the preceding context, the darker the color, and the more your eyes
should linger; where it's lighter, since it was already guessable from the preceding context, you can skim
past quickly.
*As of October 2026, the Info Highlight extension has reached over 1,000 weekly active users at its peak,
with over 5,000 total likes, saves, and shares across social platforms.
Ideal vs Reality
For an ideal model, whose knowledge and contextual understanding match that of the reader, the evaluation
would perfectly align with human subjective perception.
Therefore, the gap between current results and reader perception mainly comes from two aspects:
Model capability vs human reader: The model's understanding and knowledge may be generally less than,
or possibly exceed, the reader's. Imagine comparing a state-of-the-art LLM with a ten-year-old reader.
Model context vs human reader: The model only has the text read so far as context, much less
than the reader's. Info Highlight uses base models without instruction tuning or prompts (which actually
gives the best results).
The good news is that LLMs are improving so fast: current analysis results already reflect mainstream
readers' subjective perception to some extent, and can be used to evaluate article information content and
improve reading speed.
Highlighting of errors and random content
Attentive readers may notice that bad grammar, factual errors, and even random content can still light up
strongly. Is that reasonable?
As noted earlier, our core assumption is that the magnitude of conditional information is related to human
subjective perception—not identical to it:
Word importance in text≤conditional information of the token in the context
What we can say for sure is that important content must be hard to predict (and will highlight), or
equivalently, easy-to-predict content (little highlight) cannot be very important. If it is easy to guess,
how much information can it carry? But hard-to-predict content is not necessarily important—for example,
erroneous content or random content.
Still, from some angles, erroneous and random content may carry its own kind of information: the fact that an
article contains an error, that someone misspoke, or that a stretch of text is a random key—all of these
can plausibly “contain information,” so highlighting them rather than leaving them dim may be the more
reasonable choice.
Why does information content affect text quality?
Low information content means the LLM can easily predict it from context. If even a machine can predict it,
how important can it be? Conversely, high information content means the LLM has difficulty predicting it
from context. (Assuming it's not a mistake) Then it represents key information the author wants to convey
that the machine doesn't know.
Timeline and Outlook
In the 1940s: Shannon information theory laid the foundations.
Around 2000, several key ideas pointed toward regularity in the information-theoretic nature of language:
Entropy Rate Constancy (ERC) hypothesis: a word's absolute entropy increases with position, while conditional entropy stays roughly constant across the text (Genzel & Charniak, 2002).
Uniform Information Density (UID) hypothesis: humans tend to distribute information as evenly as possible across the text—like an “information smoothing pressure” that releases information gradually (Jaeger, 2010).
Surprisal Theory: surprisal correlates almost linearly with reading time / processing difficulty (Hale, 2001; Levy, 2008).
After 2018, large language models emerged:
Shared next-word prediction in brains and models: both continuously predict the next word and update from prediction error (Goldstein et al., 2022).
Average per-word surprisal predicts reading ease: remarkably robust across model sizes (Gruteke Klein et al., 2025).
In 2025, Info Highlight pioneered using LLMs to compute surprisal for reading assistance, and open-sourced the code.
Looking ahead: LLMs × information theory—what cognitive breakthroughs might this bring for language? Are we on the eve of re-understanding the information-theoretic nature of language?
参考文献References
Shannon, C. E. (1951). Prediction and entropy of printed English. Bell System Technical Journal,
30(1), 50–64. doi.org
Hale, J. (2001). A probabilistic Earley parser as a psycholinguistic model. In Proceedings of
NAACL. aclanthology.org
Levy, R. (2008). Expectation-based syntactic comprehension. Cognition, 106(3), 1126–1177. doi.org
Genzel, D., & Charniak, E. (2002). Entropy rate constancy in text. In Proceedings of ACL
(pp. 199–206). aclanthology.org
Jaeger, T. F. (2010). Redundancy and reduction: Speakers manage syntactic information density.
Cognitive Psychology, 61(1), 23–62. doi.org
Gehrmann, S., Strobelt, H., & Rush, A. M. (2019). GLTR: Statistical detection and visualization of
generated text. In Proceedings of ACL 2019: System Demonstrations (pp. 111–116). doi.org
Goldstein, A., Zada, Z., Buchnik, E., Schain, M., Price, A., Aubrey, B., … Hasson, U. (2022). Shared
computational principles for language processing in humans and deep language models. Nature
Neuroscience, 25, 369–380. doi.org
Gruteke Klein, K., Frenkel, S., Shubi, O., & Berzak, Y. (2025). Surprisal takes it all: Eye
tracking based cognitive evaluation of text readability measures. arXiv. arxiv.org/abs
Parker, A. J., Wang, H., Lee, H., & Joseph, H. (2026). Does the selective bolding of characters
within words improve reading performance in skilled adult readers? Evidence from eye movements.
Royal Society Open Science, 13(9), Article 250177. doi.org
致谢
基于 2019 年 Hendrik Strobelt 等人开发的经典项目 GLTR.io。GLTR 是一个网页演示,率先用 GPT-2 的预测概率来检测生成文本。
不过信息高亮 (Info Highlight) 的目标不是检测 AI 文本,而是评估文本的“信息质量”。
Built on the classic project GLTR.io,
developed by Hendrik Strobelt et al. in 2019. GLTR was a web demo that pioneered using GPT-2 prediction
probabilities to detect generated text.
However, Info Highlight is not meant to detect AI text, but to evaluate the "information quality" of text.
FAQ
Is it an AI text detector?
No.
When we dislike AI text, we actually dislike low-quality text. We dislike low-quality human-written text,
rather than high-quality AI-generated content. So the key is the "information quality" of the text.
Info Highlight aims to detect "information quality" rather than "AI signs", though it can be used to detect
AI-generated nonsense with no information content.
What LLM is currently used?
Currently the open-source Qwen3-0.6B/1.7B/4B/14B-Base family is used. Among the models the
author has tested, 0.6B comes closest to most people's subjective perception. Larger models
sometimes "know" too much: they predict continuations more easily, so highlights grow sparser and feel less
like everyday reading habits (a bigger model is not necessarily a better match for subjective perception).
This site defaults to 0.6B; when hardware allows, larger models are also available. Their scores typically
differ from 0.6B by within ~15% and follow a similar trend, but the highlighting often looks thinner.